
AI Training vs Inference: What Is the Difference?
 AI Training vs Inference: What Is the Difference?
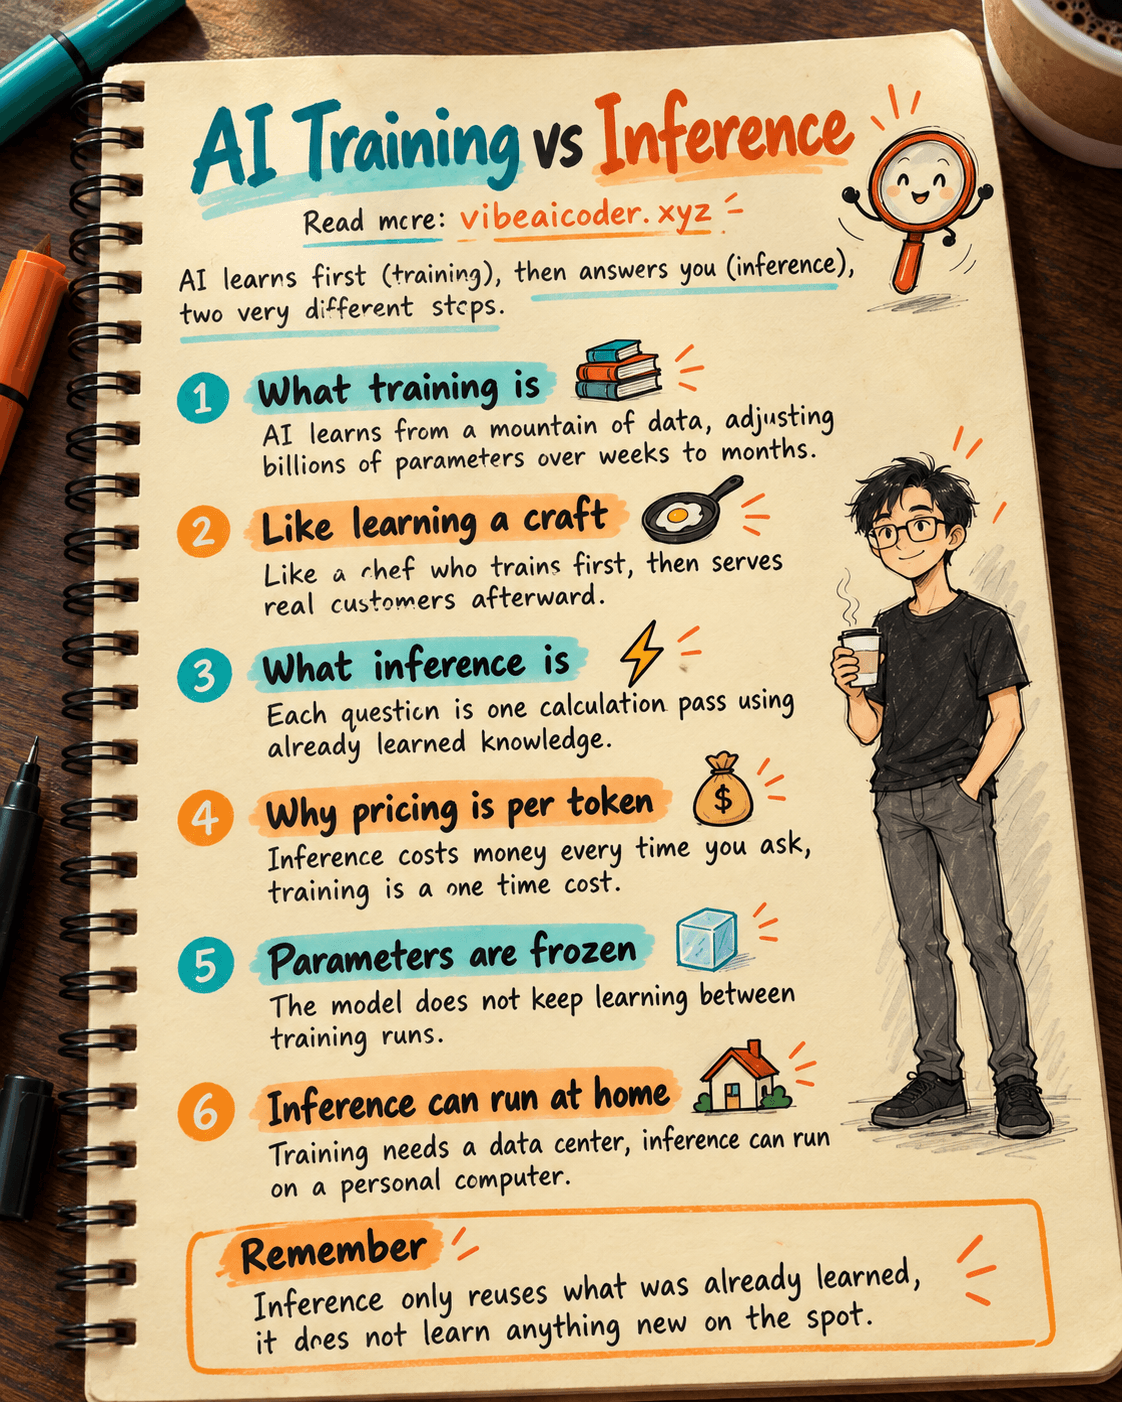
Training is the stage where AI learns from a mountain of data to figure out how to answer, much like an apprentice practicing a craft thousands of times before going pro. Inference is when that AI, already trained, uses what it learned to answer your new question right on the spot, without learning anything new. Understanding this difference makes AI news easier to follow, explains why some AI apps answer fast while others are slower, and clears up why your AI bill is calculated the way it is.
 An Everyday Analogy
Picture a chef in training. For years, this person cooks the same dishes over and over, tastes them, gets corrected by a mentor, and adjusts technique after every mistake. That is training: it costs enormous time and effort, but it only has to happen once.
Once qualified, the chef works the line serving real customers. A customer orders, the chef cooks right away using the skills already built up, with no need to relearn anything from scratch for each new order. If a dish does not turn out great that day, the chef does not "relearn" on the spot either, only the skills already practiced are available. That is inference: much faster than training, but limited to whatever was taught beforehand.
AI works the same way. Training is when the model "goes to school." Inference is every time you open Claude or ChatGPT and ask a question, as if the AI is bringing its learned knowledge out to serve exactly what you asked for. If you are not familiar with how AI works in general, read what is AI first.
 How It Actually Works
- Gather a massive dataset: books, web pages, source code, sample conversations, all collected into a training dataset.
- Training: the model makes a prediction (for example, guessing the next word), compares it to the correct answer, and nudges billions of internal numbers called parameters. You can read more about parameters in what are AI parameters. This step repeats billions of times, running for weeks to months across thousands of dedicated GPU or TPU chips working in parallel.
- Freeze the parameters: once training finishes, every number the model learned gets "frozen" into one fixed model version. The model will not change again until the next training run.
- Inference: when you type a question, the model uses that frozen set of parameters to compute an answer. This is just one forward pass of calculation (no correction step, no parameter update), so it is far lighter than training.
- Repeat for every question: each message you send is a new, independent inference pass, using the same already-trained brain rather than "reviewing the material" each time.
Because inference is so much lighter than training, it can run on a phone or a personal computer, while training needs an entire data center. If you are curious about running an AI model on your own machine, running AI locally explains how powerful your machine needs to be, and that is still just running inference, not training a model from scratch.
 What This Means for You
- When you chat with Claude or ChatGPT, you are only using the inference stage. The model does not instantly learn more from your conversation to get smarter within that same session.
- News like "training the next model cost hundreds of millions of dollars" does not contradict "pricing is just a few dollars per million tokens." Training cost is a massive one-time investment that covers the model's entire lifespan. Inference cost is small, charged per question you send, which is why API plans bill by input and output tokens. How AI pricing works breaks this down further.
- If you want AI to "remember" your own information forever, you need a form of retraining called fine-tuning. If you only need the AI to know that information for one conversation or one query, just paste it into the prompt, no training step required at all.
- When comparing AI apps, differences in response speed mostly come down to inference running on different hardware, not one app "still learning" while another "already knows."
 Common Misconceptions
- "Every time I chat, the AI is learning immediately." In reality, a chat session is usually just inference, the model's parameters do not change right then. If a provider later folds conversation data into a future training run, that happens afterward, in large batches, and usually comes with a privacy setting you can turn on or off.
- "Inference is always cheap and equally fast." Inference still costs real compute, which is why it is billed by token. With a long question, multiple attached files, or a "deep reasoning" mode, a single inference pass can be much slower and more expensive than a simple answer.
- "A model that reasons through many steps is being retrained." The word "reasoning" trips people up here. Inference is the model computing an answer, whether that takes one step or many. A "reasoning model" is simply a model trained to write out more thinking steps before settling on an answer, but that process still belongs to inference, not retraining.
 FAQ
How long does it take to train a large AI model? Depending on scale, today's leading models typically take a few weeks to a few months of continuous training across thousands of dedicated GPU or TPU chips, costing anywhere from tens to hundreds of millions of dollars.
Does inference make a model smarter over time? No. Inference only uses already-learned knowledge to answer, it does not change the model's internal parameters. A model only gets "better" when developers train and release a new version.
Why does AI sometimes answer slower than usual? Because that particular inference pass needs more computation, for example a long question, several attached files, or a deep reasoning mode. All of that is still inference, just a heavier pass than usual.
Can I train an AI like Claude myself at home? Training a model at that scale from scratch is not feasible on a personal computer. But you can absolutely run inference yourself with smaller open source models on your own machine, or lightly fine-tune a small model for your own needs.
Is fine-tuning the same as training from scratch? No. Fine-tuning only adjusts an already-trained model using a much smaller amount of data, to make it better at one specific task, rather than learning everything again from zero.
More articles

Gemini 4 Argon Reads a 500-Page Chemistry Patent in One Afternoon

Claude Opus 5.5 Codes a Real Money Trading Game in One Day

What Is a Token in AI? Why ChatGPT and Claude Charge by Tokens

What Is Chain of Thought? Why Asking AI to Think Step by Step Works Better

Claude Sonnet 5.5 vs GPT-6.1 Sol: Which AI Model Is Worth Using?
 Claude Opus 5.5 Launches: 30% Faster, 40% Cheaper, Blocks AI Brain Copying